Introduction
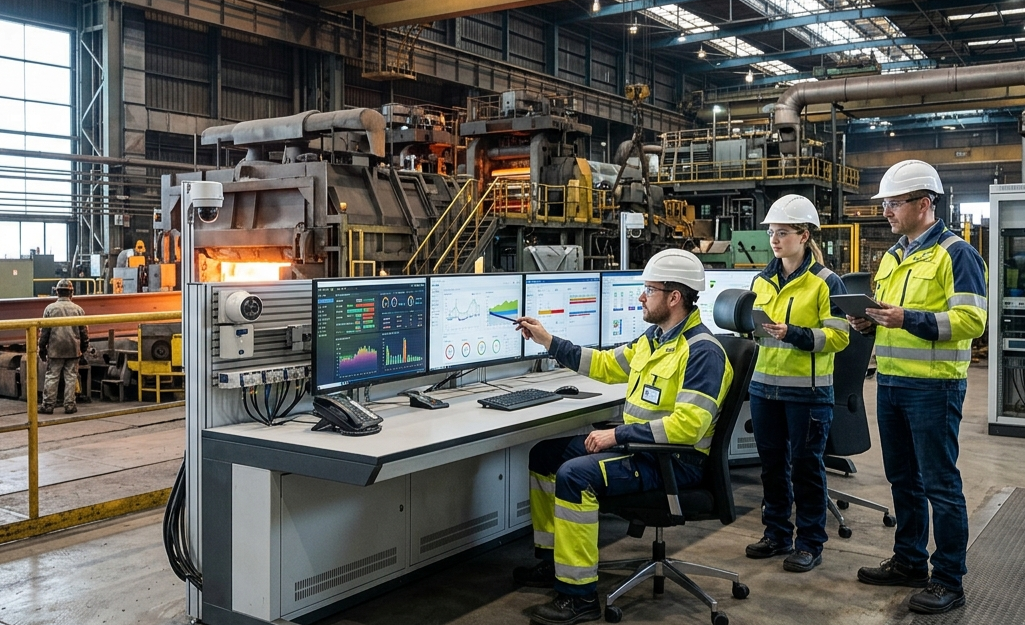
Manufacturing Execution System (MES) case studies highlight how manufacturers overcome fragmented systems, delayed data, and unreliable operational insights. In high-precision industries like steel manufacturing, these challenges directly impact productivity, traceability, and decision-making. This case study explores how a steel manufacturing enterprise implemented a custom MES integrated with enterprise systems to unify operations, improve data accuracy, and enable real-time production visibility.
Customer
A Caribbean and Central America–based steel manufacturing enterprise operating large-scale production facilities.
Business Objective
- Eliminate manual data entry and fragmented systems
- Improve trust and accuracy of operational data
- Enable real-time production visibility
- Achieve end-to-end traceability across manufacturing lifecycle
Scope of Services
- Custom MES platform design and deployment
- Integration with ERP systems (SAP)
- Real-time production data capture and monitoring
- Dashboard and KPI visualization
- Workflow digitization replacing paper and Excel-based systems
Key Challenges Addressed
- Slow and unreliable data impacting decision-making
- Manual processes using Excel, paper, and disconnected tools
- Lack of trust in MES outputs among operators
- Poor traceability across production lifecycle
Benefits
- Unified plant-floor and enterprise data
- Improved operator trust and adoption
- Real-time KPI visibility
- Reduced errors from manual processes
Impact
- End-to-end traceability from raw material to finished goods
- Real-time production insights enabling faster decisions
- Significant reduction in manual intervention and errors
Introduction
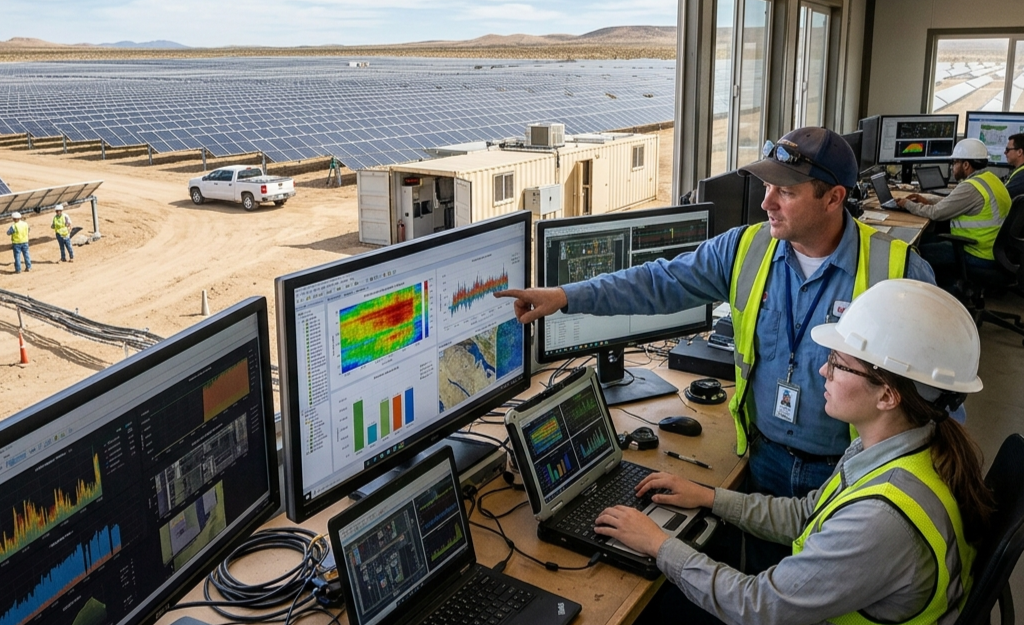
Large-scale renewable energy environments generate massive volumes of data from distributed assets, making real-time monitoring, interoperability, and analytics critical for performance optimization. However, fragmented systems and inconsistent data capture often limit visibility and slow decision-making. This case study highlights how a solar research and testing environment implemented a centralized Digital Twin framework to unify data, improve operational visibility, and enable real-time analytics. By integrating diverse systems into a single intelligent platform, the organization enhanced research accuracy, maintenance responsiveness, and scalability.
Customer
A North America–based renewable energy research organization managing a large-scale solar testing facility with thousands of distributed energy assets.
Business Objective
- Enable unified data capture across diverse solar assets and systems
- Improve real-time monitoring and operational visibility
- Enhance research accuracy through high-frequency data collection
- Reduce maintenance delays and improve response time
- Build a scalable platform for future expansion
Scope of Services
- Design and implementation of a centralized Digital Twin platform
- Integration of heterogeneous devices, systems, and protocols
- Real-time data ingestion and visualization enablement
- Development of analytics dashboards and KPI tracking
- Data consolidation into a unified database architecture
- Standardization of asset models for scalability and future onboarding
Key Challenges Addressed
- Lack of interoperability across multiple systems and vendors
- Limited visualization and absence of real-time monitoring
- Low-frequency data capture impacting research accuracy
- Fragmented data storage across platforms
- Difficulty in scaling and adding new assets
Benefits
- Unified visibility across all solar assets and systems
- Real-time monitoring enabling proactive decision-making
- Improved data accuracy and research insights
- Faster maintenance response and issue resolution
- Scalable architecture supporting future expansion
Impact
- Real-time data capture improved from low-frequency to near real-time intervals (every few seconds)
- Centralized platform enabled complete operational visibility across solar fields
- Faster maintenance response through real-time monitoring and alerts
- Scalable system design allowing seamless addition of new assets and devices
Introduction
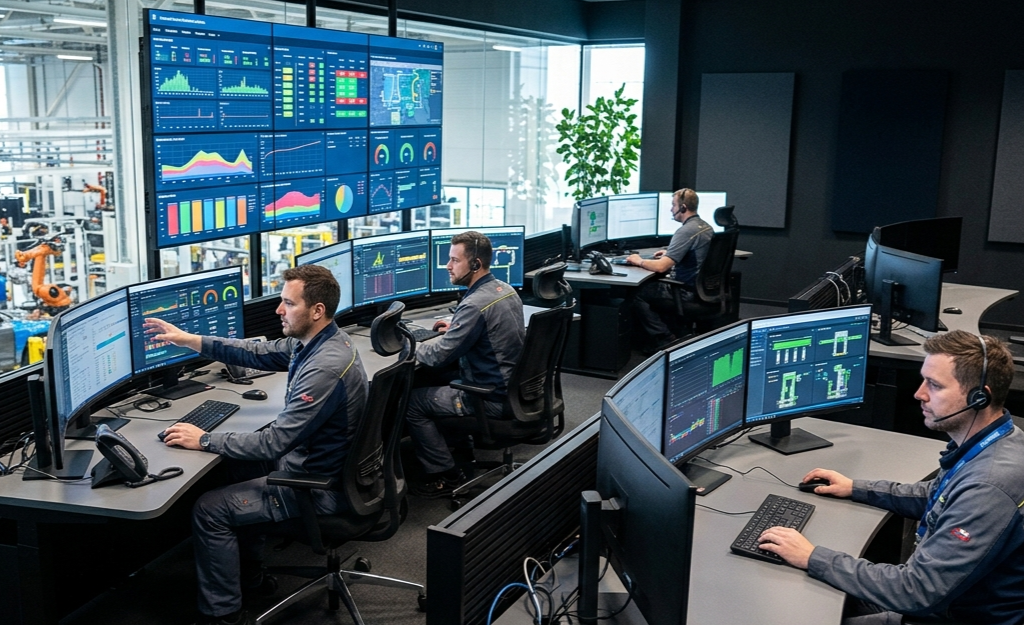
Automotive enterprises operate complex IT environments across datacenters, SAP, MES, and enterprise applications. High volumes of manually logged incidents, false alerts, and delayed resolution impact operational efficiency and system reliability. This case study highlights how an automotive leader transformed its IT operations using predictive self-healing and automation. By enabling event correlation, alert suppression, and automated resolution, the organization significantly reduced manual intervention, improved system stability, and enhanced operational efficiency.
Customer
A leading automotive enterprise managing large-scale datacenter operations, enterprise applications, and manufacturing systems across global operations.
Business Objective
- Reduce manual ticket logging and operational overhead
- Minimize false alerts and improve monitoring accuracy
- Reduce P1/P2 incidents impacting critical systems
- Enable predictive and automated incident resolution
- Improve IT operations efficiency and reliability
Scope of Services
- Datacenter and IT incident pattern analysis
- Event correlation and alert suppression design
- Automation of service requests and incident resolution
- Predictive monitoring across SAP, MES, and infrastructure
- Self-healing workflow enablement across IT environments
Key Insights from Analysis
- 51%+ issues logged manually → major inefficiency
- False positives increased up to 19%
- P1/P2 incidents driven by:
- SAP security issues
- MES engine failures
- SAP HCM downtime
- Backup failures
- Automation potential identified across service requests and incidents
Detailed Findings
- High dependency on manual incident logging and handling
- Lack of effective alert correlation leading to noise
- Inefficient prioritization causing delays in critical incidents
- High recurrence of issues across SAP, MES, and infrastructure
- Significant automation gaps across EUC, DC, and network
Benefits
- Reduced manual intervention through automation
- Improved monitoring accuracy with alert suppression
- Faster incident detection and resolution
- Improved system stability and uptime
- Enhanced efficiency across IT operations
Impact
- 44% of processes identified as automatable
- 40–50% automation potential across service requests and incidents
- Significant reduction in false alerts and operational noise
- Reduced P1/P2 incidents across critical systems
- Improved operational efficiency and service reliability
Introduction
Manufacturing operations rely heavily on efficient IT support across infrastructure, applications, and core services. Rising ticket volumes, poor classification, and lack of structured service management create inefficiencies, slow resolution, and increased operational costs. This case study highlights how a cement producer transformed its IT operations by combining self-service enablement with automation and process standardization. By improving service catalogue design, governance, and automation readiness, the organization enhanced efficiency, reduced operational load, and improved service delivery.
Customer
A cement manufacturing enterprise managing large-scale IT infrastructure, applications, and support services across plant operations.
Business Objective
- Reduce rising IT ticket volumes and operational load
- Improve service efficiency through self-service and automation
- Standardize ITSM processes and governance
- Enhance response and resolution times
- Enable scalable and cost-efficient IT operations
Scope of Services
- Ticket baseline and trend analysis across incidents and service requests
- ITSM process alignment (incident vs service request classification)
- Service catalogue design and digitization
- Business priority and IT severity standardization
- Automation opportunity identification across IT domains
- Integration of incident classification, governance, and workflows
Key Insights from Analysis
- 36,107 total tickets analyzed
- 31,255 incidents vs 4,852 service requests (heavy incident skew)
- 2025 ticket volume already reached 75% of 2024 within 5 months
- Incidents surged to 80% of previous year volume
- IT core support demand increased by 10% YoY
Detailed Findings
- Process Issues (47%) → Lack of structured classification and ITSM governance
- Security Issues (18%) → Need for compliance, SOX alignment, and governance
- Hardware Issues (10%) → Gaps in lifecycle and service catalogue alignment
- Software Issues (8%) → Need for digitalization and automation
- Network Issues (7%) → Performance and monitoring gaps
Benefits
- Improved ticket handling through structured ITSM processes
- Reduced manual intervention via self-service enablement
- Better SLA adherence through prioritization and governance
- Improved visibility into IT operations and performance
- Enhanced scalability of IT support operations
Impact
- 20%–24% automation potential identified
- 40% automation opportunity in security-related issues
- Clear segregation of incidents vs service requests
- Reduced dependency on manual support processes
- Improved efficiency across IT infrastructure and applications
Introduction
Manufacturing plants depend on stable IT systems across EUC, SAP, network, and application environments to ensure uninterrupted production. High ticket volumes, manual intervention, and delayed resolution directly impact plant uptime and operational efficiency. This case study highlights how a cement manufacturer transformed its IT operations using AI-driven self-healing and automation. By analyzing ticket patterns, standardizing processes, and enabling automation at scale, the organization significantly improved efficiency, reduced incidents, and enhanced plant uptime.
Customer
A cement manufacturing enterprise managing large-scale plant operations with high IT dependency across EUC, SAP, network, and application environments.
Business Objective
- Reduce IT ticket volumes and operational load
- Improve plant uptime and operational efficiency
- Minimize SLA breaches and turnaround time
- Enable automation-led IT operations
- Improve service quality across IT environments
Scope of Services
- Baseline ticket analysis across EUC, SAP, network, and applications
- Ticket classification and severity alignment
- Service catalogue rationalization and digitization
- Automation opportunity identification and implementation
- AI-driven event correlation and self-healing enablement
- ITSM process standardization and optimization
Key Insights from Analysis
- 11,586 total tickets analyzed (Jan–Aug 2025)
- Ticket volume increased by 33% in recent months
- Majority tickets categorized as Moderate severity (10,771)
- EUC accounted for 6,412 tickets (largest contributor)
- Significant inefficiencies in ticket classification and prioritization
Detailed Findings
- Process Issues (27%) → Misclassification and lack of structured ITSM taxonomy
- EUC Issues (51%) → High dependency on manual support and outdated service catalogue
- SAP Issues (47%) → Need for lifecycle alignment and better business integration
- Hardware Issues (17%) → Gaps in service catalogue and storage/EUC alignment
Benefits
- Improved ticket handling efficiency through automation
- Reduced manual intervention in recurring incidents
- Faster incident prioritization and resolution
- Better SLA adherence across IT services
- Improved visibility and control over IT operations
Impact
- 48.33% overall automation potential identified
- 47% efficiency potential in process-related issues
- 29% efficiency improvement opportunity in EUC
- 19% efficiency opportunity in SAP
- Reduction in manual ticket handling and operational load
- Improved plant uptime and IT service reliability
Introduction
Manufacturing efficiency in discrete operations depends heavily on accurate data capture, classification, and real-time measurement of performance metrics such as OEE (Overall Equipment Effectiveness). However, inconsistent data capture, manual interventions, and unreliable PLC logic often lead to incorrect insights, masking true efficiency and impacting decision-making. This case study highlights how an AI–IIoT–enabled framework was conceptualized to address these challenges. By improving data accuracy, automating classification, and standardizing implementation across plants, the organization aimed to unlock true production visibility and operational efficiency.
Customer
A manufacturing organization with operations across forging, drilling, and injection moulding processes, facing challenges in efficiency measurement, data capture, and workforce usability.
Business Objective
- Improve accuracy of downtime vs. changeover classification
- Enable reliable rejection and rework data capture
- Enhance production efficiency measurement beyond planned vs. achieved metrics
- Strengthen PLC/IoT-based data capture for manual operations
- Standardize IoT implementation across plants
Scope of Services
- Design of AI–IIoT–enabled framework for manufacturing operations
- Automation of downtime and changeover classification
- Enablement of conditional rejection and rework data handling
- Implementation of advanced efficiency metrics beyond basic production tracking
- Enhancement of PLC/IoT logic with anomaly detection
- Standardization of IoT data capture across multiple plants
Key Challenges Addressed
- Misclassification of downtime vs. changeover due to flawed timestamp logic
- Delayed and inaccurate rejection/rework data entry
- Misleading efficiency metrics masking real production performance
- Inconsistent pulse capture in manual drilling operations
- Fragmented IoT adoption across different manufacturing units
Benefits
- Accurate classification of production events and improved OEE visibility
- Reduced dependency on manual data entry and intervention
- Improved quality data accuracy for rejection and rework analysis
- Better alignment of efficiency metrics with real production performance
- Standardized and scalable IoT implementation across plants
Impact
- Improved production accuracy and operational visibility
- Enhanced workforce usability and reduced manual intervention
- Better decision-making through reliable efficiency metrics
- Foundation for scalable AI–IIoT adoption in discrete manufacturing environments
Introduction
Predictive IT operations enable enterprises to move from reactive incident handling to proactive and intelligent service management. Automotive manufacturers operating complex IT ecosystems often face high incident volumes, false alerts, and critical system failures across SAP, MES, and enterprise platforms. These challenges impact operational efficiency and increase downtime risks. This case study highlights how a leading automotive manufacturer implemented predictive analytics and observability-driven automation to improve incident management, reduce noise, and enable self-healing IT operations across its datacenter and enterprise systems.
Customer
A leading automotive manufacturer managing large-scale datacenter operations and enterprise systems including SAP, MES, HCM, and network infrastructure.
Business Objective
- Reduce manual ticket handling and operational load
- Minimize false positives and alert noise
- Reduce P1/P2 incidents and critical failures
- Enable predictive and automated incident resolution
- Improve efficiency across IT operations
Scope of Services
- Analysis of IT incident patterns and event behavior
- Event classification and severity alignment
- Alert correlation and false-positive reduction
- Automation of service requests and incident resolution
- Predictive monitoring across SAP, MES, HCM, and infrastructure systems
Benefits
- Reduced alert noise and false positives
- Improved accuracy in incident detection and prioritization
- Faster response and resolution of critical issues
- Enhanced reliability of enterprise systems
- Better operational visibility through observability platforms
Impact
- 51% of manually logged issues identified for automation
- 40–50% automation potential across incidents and requests
- 44% of total incidents identified as automatable
- Significant reduction in P1/P2 incidents
Introduction
ITSM optimization is critical for manufacturing organizations handling high volumes of IT service requests across complex environments. Large-scale cement operations often experience rising ticket volumes across infrastructure, applications, and security systems, leading to inefficiencies and increased operational load. This case study highlights how a cement producer improved IT service efficiency by implementing structured ITSM optimization and ticket intelligence. By analyzing ticket patterns, enabling self-service, and standardizing workflows, the organization built a strong foundation for scalable automation and improved service delivery.
Customer
A cement producer operating large-scale manufacturing facilities with high volumes of IT service requests across infrastructure, applications, and support environments.
Business Objective
- Reduce IT ticket volumes and operational load
- Improve efficiency through self-service and automation readiness
- Optimize incident vs service request handling
- Enhance response times and service availability
- Improve cost efficiency across IT operations
Scope of Services
- Baseline analysis of IT tickets and service requests
- Ticket classification and automation readiness assessment
- Service catalogue design and digitization
- Process alignment for ITSM workflows and prioritization
- Identification of automation and self-service opportunities
- KPI-driven optimization of IT service operations
Benefits
- Improved efficiency in ticket handling and service delivery
- Reduced manual intervention in repetitive issues
- Better visibility into ticket patterns and root causes
- Clear segregation of incidents and service requests
- Improved prioritization aligned with business KPIs
Impact
- 36,107 tickets analyzed across environments
- Identification of 20–24% automation potential
- 40% automation efficiency potential in security issues
- 47% of tickets attributed to process-related issues
- Reduced dependency on manual ticket resolution
Introduction
AI-driven self-healing IT operations enable manufacturing organizations to reduce downtime, improve service efficiency, and optimize IT support at scale. A cement manufacturing company operating large-scale plants faced high volumes of IT service tickets across EUC, SAP, network, and application environments. Manual handling led to delays, SLA breaches, and operational inefficiencies that directly impacted plant uptime. By implementing self-healing IT operations and ITSM automation, the organization transformed its IT support model, reduced manual effort, and improved service reliability across critical systems.
Customer
A cement manufacturing company managing large-scale plant operations with high IT service ticket volumes across multiple technology environments.
Business Objective
- Reduce IT incidents and SLA breaches
- Improve turnaround time (TAT) for issue resolution
- Minimize manual effort in IT support operations
- Enhance plant uptime and operational efficiency
- Enable automation-driven IT service management
Scope of Services
- ITSM process alignment and event categorization
- Ticket classification for incidents and service requests
- Automation across EUC, SAP, applications, and network
- Proactive monitoring and automated ticket handling
- Service catalogue digitization and rationalization
- Identification and implementation of automation opportunities
Benefits
- Reduced turnaround time and SLA impact
- Improved service quality through automated resolution
- Lower manual dependency and fewer operational errors
- Faster incident prioritization and response
- Improved efficiency across IT support functions
Impact
- 11,586 tickets analyzed (Jan–Aug 2025)
- 1.32M+ transactions automated annually
- 97,000+ FTE hours saved annually
- 49 bots deployed in production
- 16 processes automated
- 48.33% automation potential identified
- Significant reduction in EUC, SAP, and process-related incidents
Introduction
Scalable platform deployment enables capital-heavy manufacturing organizations to modernize operations without committing to large upfront investments. Traditional transformation programs often require significant capital expenditure, creating hesitation and slowing adoption. This case study highlights how a manufacturing enterprise adopted modular, service-based platforms to reduce financial risk and accelerate return on investment. By shifting from a CAPEX-heavy approach to a scalable OPEX-driven model, the organization enabled faster deployment, improved flexibility, and aligned technology investments with business growth.
Customer
A capital-heavy manufacturing organization cautious about large upfront investments and seeking flexible technology adoption models.
Business Objective
- Minimize upfront capital expenditure
- Achieve faster return on investment
- Reduce financial risk in transformation initiatives
- Enable scalable and phased technology adoption
- Improve confidence in technology investments
Scope of Services
- Deployment of modular, scalable platforms
- Implementation of service-based delivery models
- Phased rollout aligned with business priorities
- Enablement of flexible scaling across operations
- Optimization of cost and investment structures
Benefits
- Reduced financial risk through phased investments
- Flexible scaling aligned with business demand
- Lower barrier to technology adoption
- Improved alignment between cost and value realization
- Increased agility in decision-making
Impact
- Faster ROI cycles across initiatives
- Improved stakeholder confidence in technology investments
- More efficient allocation of capital resources