Introduction
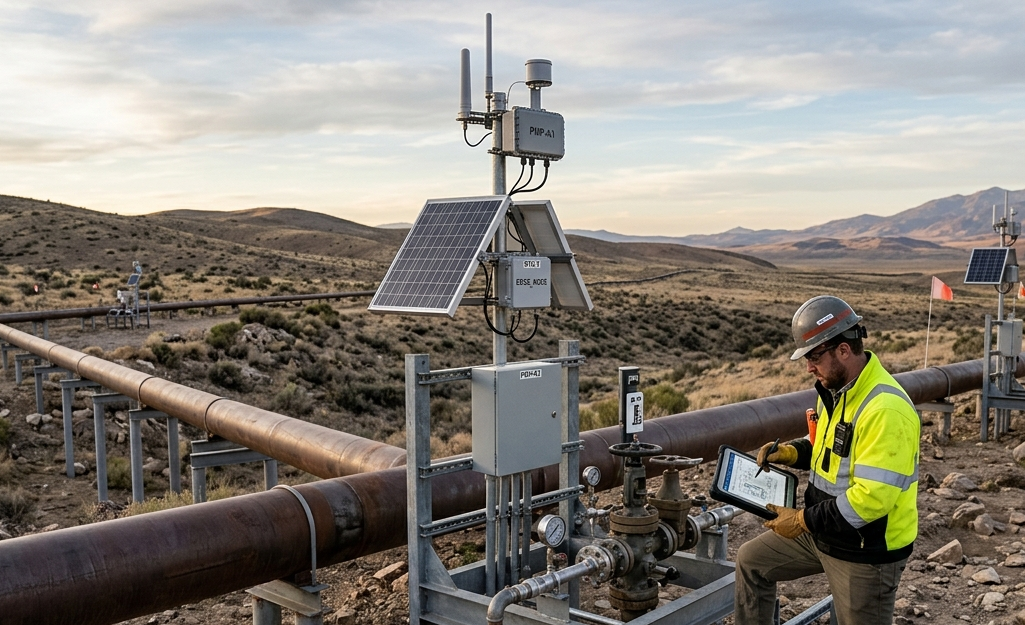
Oil and gas infrastructure operates across remote and harsh environments, requiring reliable data collection and real-time monitoring. Legacy systems often introduce complexity, high costs, and scalability challenges. This case highlights how a modern MQTT-based architecture transformed data flow, reduced complexity, and enabled scalable operations. The approach focused on simplifying communication layers while ensuring reliable and secure data transmission from distributed assets.
Customer
A US-based oil and gas infrastructure provider managing large-scale pipeline networks. The organization operates across geographically dispersed locations, requiring continuous monitoring and coordination to maintain operational safety and efficiency.
Business Objective
- Reduce network complexity and operational overhead across infrastructure
- Enable real-time data flow from remote and distributed assets
- Improve scalability of infrastructure to support expansion
- Reduce dependency on manual configuration and system updates
Scope of Services
- SCADA system modernization across pipeline monitoring systems
- MQTT-based data architecture implementation for efficient communication
- Edge device deployment across remote sites for data collection
- Centralized monitoring and control for operational visibility
Technology Used
- MQTT protocol for lightweight and efficient data transmission
- Edge gateways and IIoT architecture for remote connectivity
- SCADA + HMI systems for monitoring and control
- Real-time data analytics for operational insights
Key Challenges Addressed
- Complex VPN-based architecture and high maintenance effort
- Manual system updates across 100+ endpoints
- Lack of scalable and flexible data architecture
Benefits
- Simplified architecture and reduced system complexity
- Faster data transmission and processing across sites
- Improved scalability and flexibility for future expansion
- Reduced operational costs and maintenance effort
Impact
- Significant reduction in network complexity across infrastructure
- Faster deployment with processes reduced from hours to minutes
- Improved operational efficiency and scalable system performance
Introduction
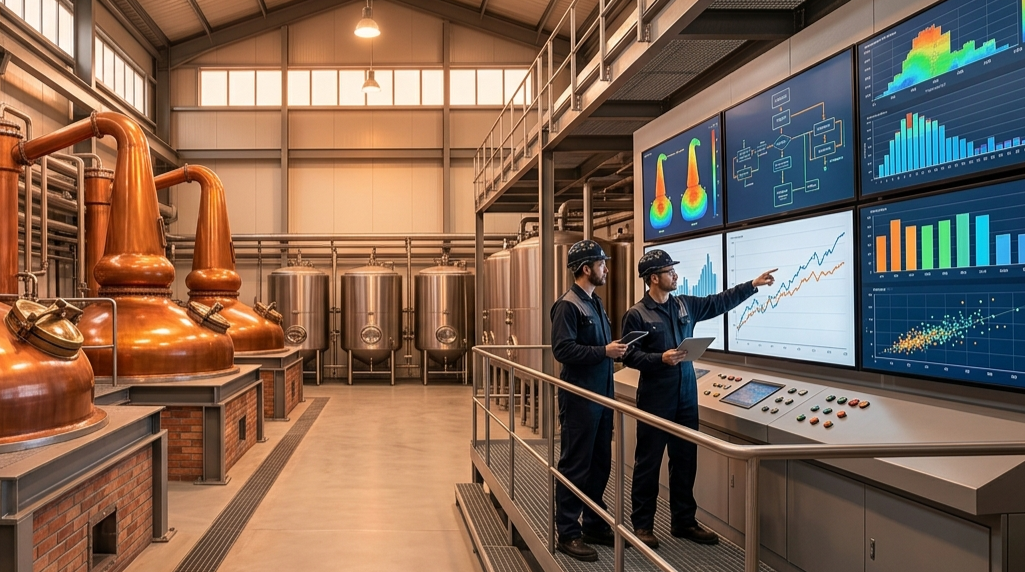
SCADA modernization case studies demonstrate how legacy manufacturing environments can evolve into data-driven operations. Traditional distilleries, especially those operating in historic facilities, often face challenges such as limited historical data, disconnected systems, and restricted physical expansion. These limitations make it difficult to optimize production processes, forecast demand accurately, and maintain consistent product quality over time.
Customer
A North America–based premium distillery operating a historic production facility. The organization is known for maintaining traditional distillation processes while ensuring high product quality and consistency across batches. The facility includes multiple stages of production such as fermentation, distillation, aging, and packaging, all operating within a physically constrained environment due to the legacy nature of the infrastructure.
Business Objective
- Improve long-term production planning using historical data
- Enable real-time visibility into production processes
- Enhance operational efficiency within physical constraints
- Modernize legacy automation systems
Scope of Services
- SCADA system modernization and replacement
- Real-time data capture and historian implementation
- HMI redesign for improved usability
- Integration across production systems
Technology Used
- SCADA + IIoT platform
- Real-time data historian
- High-performance HMI systems
- Mobile-enabled dashboards
Key Challenges Addressed
- Lack of historical data impacting long-term planning
- Limited operational visibility across production processes
- Inefficient legacy SCADA system
Benefits
- Improved data-driven decision-making
- Better production forecasting and planning
- Enhanced operator experience through modern UI
- Increased operational efficiency
Impact
- Real-time and historical data enabled long-term production planning
- Improved operational efficiency across constrained facilities
- Faster decision-making through centralized visibility
Introduction
Manufacturing Execution System (MES) case studies highlight how manufacturers overcome fragmented systems, delayed data, and unreliable operational insights. In high-precision industries like steel manufacturing, these challenges directly impact productivity, traceability, and decision-making. This case study explores how a steel manufacturing enterprise implemented a custom MES integrated with enterprise systems to unify operations, improve data accuracy, and enable real-time production visibility.
Customer
A Caribbean and Central America–based steel manufacturing enterprise operating large-scale production facilities.
Business Objective
- Eliminate manual data entry and fragmented systems
- Improve trust and accuracy of operational data
- Enable real-time production visibility
- Achieve end-to-end traceability across manufacturing lifecycle
Scope of Services
- Custom MES platform design and deployment
- Integration with ERP systems (SAP)
- Real-time production data capture and monitoring
- Dashboard and KPI visualization
- Workflow digitization replacing paper and Excel-based systems
Key Challenges Addressed
- Slow and unreliable data impacting decision-making
- Manual processes using Excel, paper, and disconnected tools
- Lack of trust in MES outputs among operators
- Poor traceability across production lifecycle
Benefits
- Unified plant-floor and enterprise data
- Improved operator trust and adoption
- Real-time KPI visibility
- Reduced errors from manual processes
Impact
- End-to-end traceability from raw material to finished goods
- Real-time production insights enabling faster decisions
- Significant reduction in manual intervention and errors
Introduction
Large-scale renewable energy environments generate massive volumes of data from distributed assets, making real-time monitoring, interoperability, and analytics critical for performance optimization. However, fragmented systems and inconsistent data capture often limit visibility and slow decision-making. This case study highlights how a solar research and testing environment implemented a centralized Digital Twin framework to unify data, improve operational visibility, and enable real-time analytics. By integrating diverse systems into a single intelligent platform, the organization enhanced research accuracy, maintenance responsiveness, and scalability.
Customer
A North America–based renewable energy research organization managing a large-scale solar testing facility with thousands of distributed energy assets.
Business Objective
- Enable unified data capture across diverse solar assets and systems
- Improve real-time monitoring and operational visibility
- Enhance research accuracy through high-frequency data collection
- Reduce maintenance delays and improve response time
- Build a scalable platform for future expansion
Scope of Services
- Design and implementation of a centralized Digital Twin platform
- Integration of heterogeneous devices, systems, and protocols
- Real-time data ingestion and visualization enablement
- Development of analytics dashboards and KPI tracking
- Data consolidation into a unified database architecture
- Standardization of asset models for scalability and future onboarding
Key Challenges Addressed
- Lack of interoperability across multiple systems and vendors
- Limited visualization and absence of real-time monitoring
- Low-frequency data capture impacting research accuracy
- Fragmented data storage across platforms
- Difficulty in scaling and adding new assets
Benefits
- Unified visibility across all solar assets and systems
- Real-time monitoring enabling proactive decision-making
- Improved data accuracy and research insights
- Faster maintenance response and issue resolution
- Scalable architecture supporting future expansion
Impact
- Real-time data capture improved from low-frequency to near real-time intervals (every few seconds)
- Centralized platform enabled complete operational visibility across solar fields
- Faster maintenance response through real-time monitoring and alerts
- Scalable system design allowing seamless addition of new assets and devices
Introduction
Banking institutions operate in high-availability environments where system downtime and delayed incident resolution directly impact customer experience and business continuity. High incident volumes during peak business hours, duplicate tickets, and manual intervention reduce operational efficiency and increase risk. This case study highlights how a banking institution improved resilience through automated healing, intelligent ticket analysis, and service recovery mechanisms. By enabling event correlation, automation, and proactive monitoring, the organization significantly enhanced system stability and operational efficiency.
Customer
A large-scale banking institution managing high-volume IT incidents across application and infrastructure environments with 24×7 support requirements.
Business Objective
- Improve IT resilience through automated healing and recovery
- Reduce high incident volumes during peak business hours
- Minimize SLA violations and improve response times
- Eliminate duplicate and redundant tickets
- Shift from reactive to proactive IT operations
Scope of Services
- Heat map–based incident analysis across time and business hours
- Identification of peak-hour incident patterns and workload spikes
- Ticket classification and automation probability analysis
- Detection of duplicate and parent-child ticket patterns
- Design and implementation of automated healing workflows
- Enablement of event correlation and alert suppression
- Establishment of 24×7 Integrated Command Centre
Key Insights from Analysis
- 17,600+ incidents analyzed
- 75% incidents occur during business hours (9 AM–6 PM)
- High-volume incident drivers:
- Password issues (22%)
- Account issues (19%)
- Connectivity issues (17%)
- Configuration issues (16%)
- Significant duplication and parent-child ticket patterns observed
Detailed Findings
- High dependency on manual ticket logging and resolution
- Lack of event correlation leading to duplicate tickets (~400–500 cases)
- Inefficient prioritization affecting response times
- Repetitive issues (password, access, configuration) ideal for automation
- High operational load during peak hours impacting service quality
Benefits
- Reduced duplicate and redundant ticket volumes
- Faster incident detection and response
- Improved SLA adherence and service reliability
- Better prioritization of critical incidents (P1/P2)
- Enhanced operational efficiency and workload management
Impact
- 30.7% automated resolution achieved
- Up to 75% automation potential for password-related issues
- Significant reduction in manual intervention
- Improved service recovery and incident handling speed
- Strong foundation for resilient, scalable IT operations
Introduction
Insurance providers operate in highly customer-centric environments where service speed, accessibility, and reliability directly impact customer trust. High volumes of support tickets, SLA violations, and manual intervention often lead to delays and poor customer experience. This case study highlights how an insurance provider transformed its support operations through self-service enablement, automation, and workload optimization. By restructuring IT support processes and introducing intelligent automation, the organization improved service efficiency, reduced operational effort, and enhanced customer trust.
Customer
An insurance provider managing high-volume application support operations across multiple channels, including web, voice, email, and automated alerts.
Business Objective
- Improve customer trust through faster and seamless support
- Reduce SLA violations in response and resolution
- Optimize support workload across L1, L2, and L3 teams
- Enable self-service and automation-led support
- Reduce dependency on manual intervention
Scope of Services
- Ticket data analysis across time, volume, and channels
- Incident vs service request classification and optimization
- SLA compliance analysis (response and resolution)
- Skill-based workload and demand analysis
- Identification of automation and self-service opportunities
- Implementation of BOT, RPA, and auto-healing use cases
- Enablement of self-help and self-service platforms
Key Insights from Analysis
- 3,100 total tickets analyzed
- ~96% tickets converted to incidents (2,988) → poor classification
- SLA violations:
- 527 response breaches
- 589 resolution breaches
- Majority tickets originated from web (2,289)
- High dependency on manual support across channels
Workload & Skill Observations
- Operations contributed 45% of total ticket volume
- Finance & Supply Chain accounted for 44%
- Top skills in demand:
- Oracle EBS (44.9%)
- .Net/C# (20.7%)
- Oracle 4GL (19.7%)
- Strong opportunity for L3 → L2 → L1 shift-left model
Detailed Findings
- Poor ticket classification between incidents and service requests
- High volume of P3 tickets (78%) indicating inefficiency in prioritization
- SLA response violations higher than resolution → process gaps
- Lack of structured service catalogue and self-service adoption
- Repetitive issues (data updates, training, access issues) suitable for automation
Benefits
- Reduced manual ticket handling through self-service
- Improved SLA compliance and response efficiency
- Better workload distribution across support levels
- Enhanced visibility into support operations and performance
- Improved customer experience and trust
Impact
- 48.11% of tickets identified for automation/self-service impact
- 37% overall effort optimization achieved
- Significant reduction in repetitive support workload
- Improved SLA adherence and faster response times
- Enhanced customer satisfaction through seamless support experience
Introduction
Automotive enterprises operate complex IT environments across datacenters, SAP, MES, and enterprise applications. High volumes of manually logged incidents, false alerts, and delayed resolution impact operational efficiency and system reliability. This case study highlights how an automotive leader transformed its IT operations using predictive self-healing and automation. By enabling event correlation, alert suppression, and automated resolution, the organization significantly reduced manual intervention, improved system stability, and enhanced operational efficiency.
Customer
A leading automotive enterprise managing large-scale datacenter operations, enterprise applications, and manufacturing systems across global operations.
Business Objective
- Reduce manual ticket logging and operational overhead
- Minimize false alerts and improve monitoring accuracy
- Reduce P1/P2 incidents impacting critical systems
- Enable predictive and automated incident resolution
- Improve IT operations efficiency and reliability
Scope of Services
- Datacenter and IT incident pattern analysis
- Event correlation and alert suppression design
- Automation of service requests and incident resolution
- Predictive monitoring across SAP, MES, and infrastructure
- Self-healing workflow enablement across IT environments
Key Insights from Analysis
- 51%+ issues logged manually → major inefficiency
- False positives increased up to 19%
- P1/P2 incidents driven by:
- SAP security issues
- MES engine failures
- SAP HCM downtime
- Backup failures
- Automation potential identified across service requests and incidents
Detailed Findings
- High dependency on manual incident logging and handling
- Lack of effective alert correlation leading to noise
- Inefficient prioritization causing delays in critical incidents
- High recurrence of issues across SAP, MES, and infrastructure
- Significant automation gaps across EUC, DC, and network
Benefits
- Reduced manual intervention through automation
- Improved monitoring accuracy with alert suppression
- Faster incident detection and resolution
- Improved system stability and uptime
- Enhanced efficiency across IT operations
Impact
- 44% of processes identified as automatable
- 40–50% automation potential across service requests and incidents
- Significant reduction in false alerts and operational noise
- Reduced P1/P2 incidents across critical systems
- Improved operational efficiency and service reliability
Introduction
Manufacturing operations rely heavily on efficient IT support across infrastructure, applications, and core services. Rising ticket volumes, poor classification, and lack of structured service management create inefficiencies, slow resolution, and increased operational costs. This case study highlights how a cement producer transformed its IT operations by combining self-service enablement with automation and process standardization. By improving service catalogue design, governance, and automation readiness, the organization enhanced efficiency, reduced operational load, and improved service delivery.
Customer
A cement manufacturing enterprise managing large-scale IT infrastructure, applications, and support services across plant operations.
Business Objective
- Reduce rising IT ticket volumes and operational load
- Improve service efficiency through self-service and automation
- Standardize ITSM processes and governance
- Enhance response and resolution times
- Enable scalable and cost-efficient IT operations
Scope of Services
- Ticket baseline and trend analysis across incidents and service requests
- ITSM process alignment (incident vs service request classification)
- Service catalogue design and digitization
- Business priority and IT severity standardization
- Automation opportunity identification across IT domains
- Integration of incident classification, governance, and workflows
Key Insights from Analysis
- 36,107 total tickets analyzed
- 31,255 incidents vs 4,852 service requests (heavy incident skew)
- 2025 ticket volume already reached 75% of 2024 within 5 months
- Incidents surged to 80% of previous year volume
- IT core support demand increased by 10% YoY
Detailed Findings
- Process Issues (47%) → Lack of structured classification and ITSM governance
- Security Issues (18%) → Need for compliance, SOX alignment, and governance
- Hardware Issues (10%) → Gaps in lifecycle and service catalogue alignment
- Software Issues (8%) → Need for digitalization and automation
- Network Issues (7%) → Performance and monitoring gaps
Benefits
- Improved ticket handling through structured ITSM processes
- Reduced manual intervention via self-service enablement
- Better SLA adherence through prioritization and governance
- Improved visibility into IT operations and performance
- Enhanced scalability of IT support operations
Impact
- 20%–24% automation potential identified
- 40% automation opportunity in security-related issues
- Clear segregation of incidents vs service requests
- Reduced dependency on manual support processes
- Improved efficiency across IT infrastructure and applications
Introduction
Manufacturing plants depend on stable IT systems across EUC, SAP, network, and application environments to ensure uninterrupted production. High ticket volumes, manual intervention, and delayed resolution directly impact plant uptime and operational efficiency. This case study highlights how a cement manufacturer transformed its IT operations using AI-driven self-healing and automation. By analyzing ticket patterns, standardizing processes, and enabling automation at scale, the organization significantly improved efficiency, reduced incidents, and enhanced plant uptime.
Customer
A cement manufacturing enterprise managing large-scale plant operations with high IT dependency across EUC, SAP, network, and application environments.
Business Objective
- Reduce IT ticket volumes and operational load
- Improve plant uptime and operational efficiency
- Minimize SLA breaches and turnaround time
- Enable automation-led IT operations
- Improve service quality across IT environments
Scope of Services
- Baseline ticket analysis across EUC, SAP, network, and applications
- Ticket classification and severity alignment
- Service catalogue rationalization and digitization
- Automation opportunity identification and implementation
- AI-driven event correlation and self-healing enablement
- ITSM process standardization and optimization
Key Insights from Analysis
- 11,586 total tickets analyzed (Jan–Aug 2025)
- Ticket volume increased by 33% in recent months
- Majority tickets categorized as Moderate severity (10,771)
- EUC accounted for 6,412 tickets (largest contributor)
- Significant inefficiencies in ticket classification and prioritization
Detailed Findings
- Process Issues (27%) → Misclassification and lack of structured ITSM taxonomy
- EUC Issues (51%) → High dependency on manual support and outdated service catalogue
- SAP Issues (47%) → Need for lifecycle alignment and better business integration
- Hardware Issues (17%) → Gaps in service catalogue and storage/EUC alignment
Benefits
- Improved ticket handling efficiency through automation
- Reduced manual intervention in recurring incidents
- Faster incident prioritization and resolution
- Better SLA adherence across IT services
- Improved visibility and control over IT operations
Impact
- 48.33% overall automation potential identified
- 47% efficiency potential in process-related issues
- 29% efficiency improvement opportunity in EUC
- 19% efficiency opportunity in SAP
- Reduction in manual ticket handling and operational load
- Improved plant uptime and IT service reliability
Introduction
Manufacturing efficiency in discrete operations depends heavily on accurate data capture, classification, and real-time measurement of performance metrics such as OEE (Overall Equipment Effectiveness). However, inconsistent data capture, manual interventions, and unreliable PLC logic often lead to incorrect insights, masking true efficiency and impacting decision-making. This case study highlights how an AI–IIoT–enabled framework was conceptualized to address these challenges. By improving data accuracy, automating classification, and standardizing implementation across plants, the organization aimed to unlock true production visibility and operational efficiency.
Customer
A manufacturing organization with operations across forging, drilling, and injection moulding processes, facing challenges in efficiency measurement, data capture, and workforce usability.
Business Objective
- Improve accuracy of downtime vs. changeover classification
- Enable reliable rejection and rework data capture
- Enhance production efficiency measurement beyond planned vs. achieved metrics
- Strengthen PLC/IoT-based data capture for manual operations
- Standardize IoT implementation across plants
Scope of Services
- Design of AI–IIoT–enabled framework for manufacturing operations
- Automation of downtime and changeover classification
- Enablement of conditional rejection and rework data handling
- Implementation of advanced efficiency metrics beyond basic production tracking
- Enhancement of PLC/IoT logic with anomaly detection
- Standardization of IoT data capture across multiple plants
Key Challenges Addressed
- Misclassification of downtime vs. changeover due to flawed timestamp logic
- Delayed and inaccurate rejection/rework data entry
- Misleading efficiency metrics masking real production performance
- Inconsistent pulse capture in manual drilling operations
- Fragmented IoT adoption across different manufacturing units
Benefits
- Accurate classification of production events and improved OEE visibility
- Reduced dependency on manual data entry and intervention
- Improved quality data accuracy for rejection and rework analysis
- Better alignment of efficiency metrics with real production performance
- Standardized and scalable IoT implementation across plants
Impact
- Improved production accuracy and operational visibility
- Enhanced workforce usability and reduced manual intervention
- Better decision-making through reliable efficiency metrics
- Foundation for scalable AI–IIoT adoption in discrete manufacturing environments